Speech-Corpus Collection Pipeline
10 Academy · 2022 · Academic project · Team project
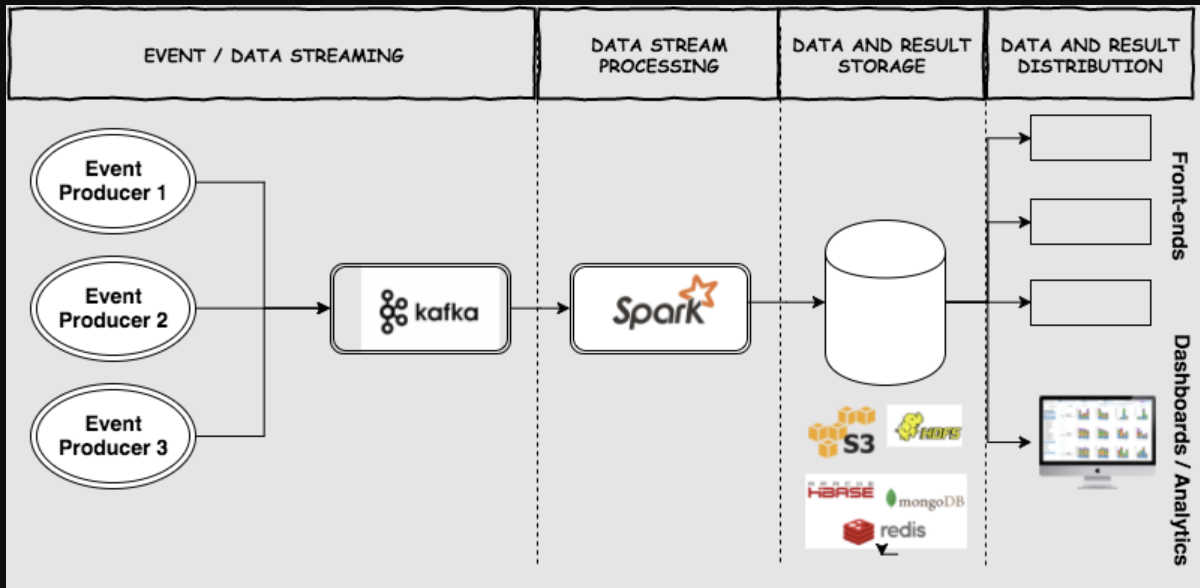
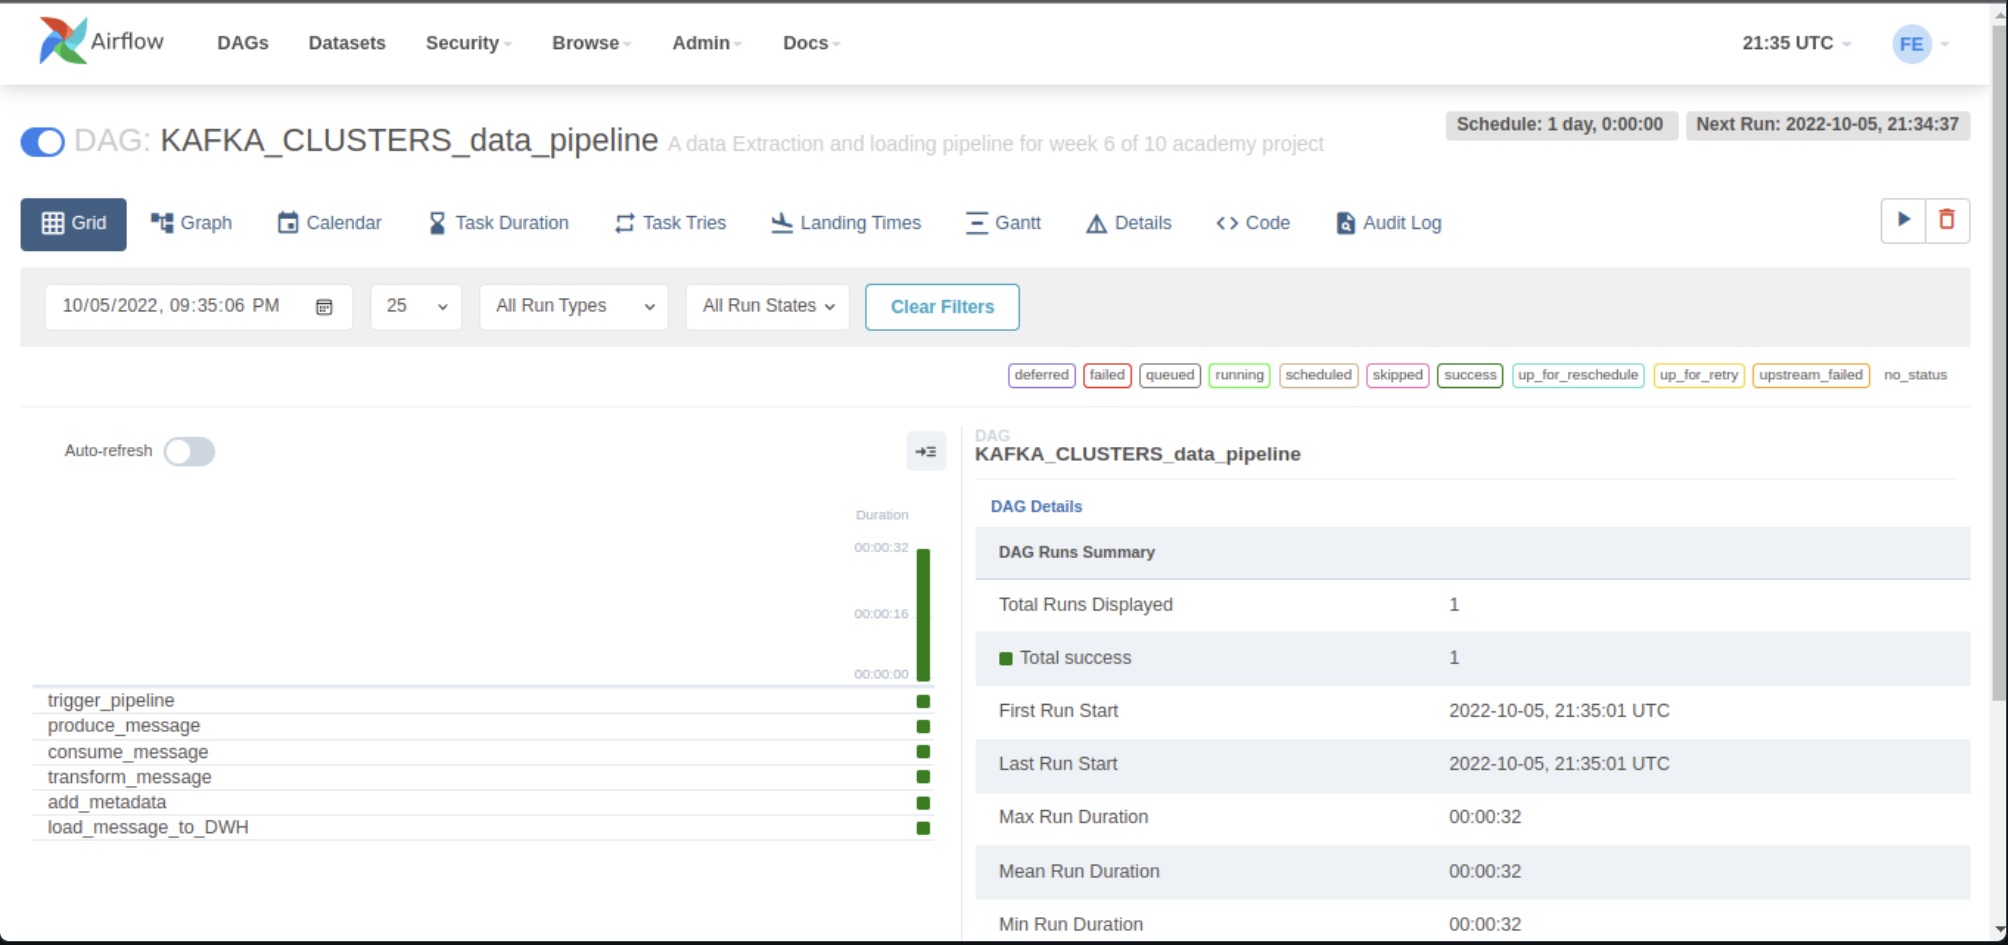
A distributed platform for collecting Amharic and Swahili speech data: Kafka streaming, Spark processing, Airflow orchestration, and S3 storage behind a React recording front-end.
- Kafka
- Spark
- Airflow
- S3
- FastAPI
Overview
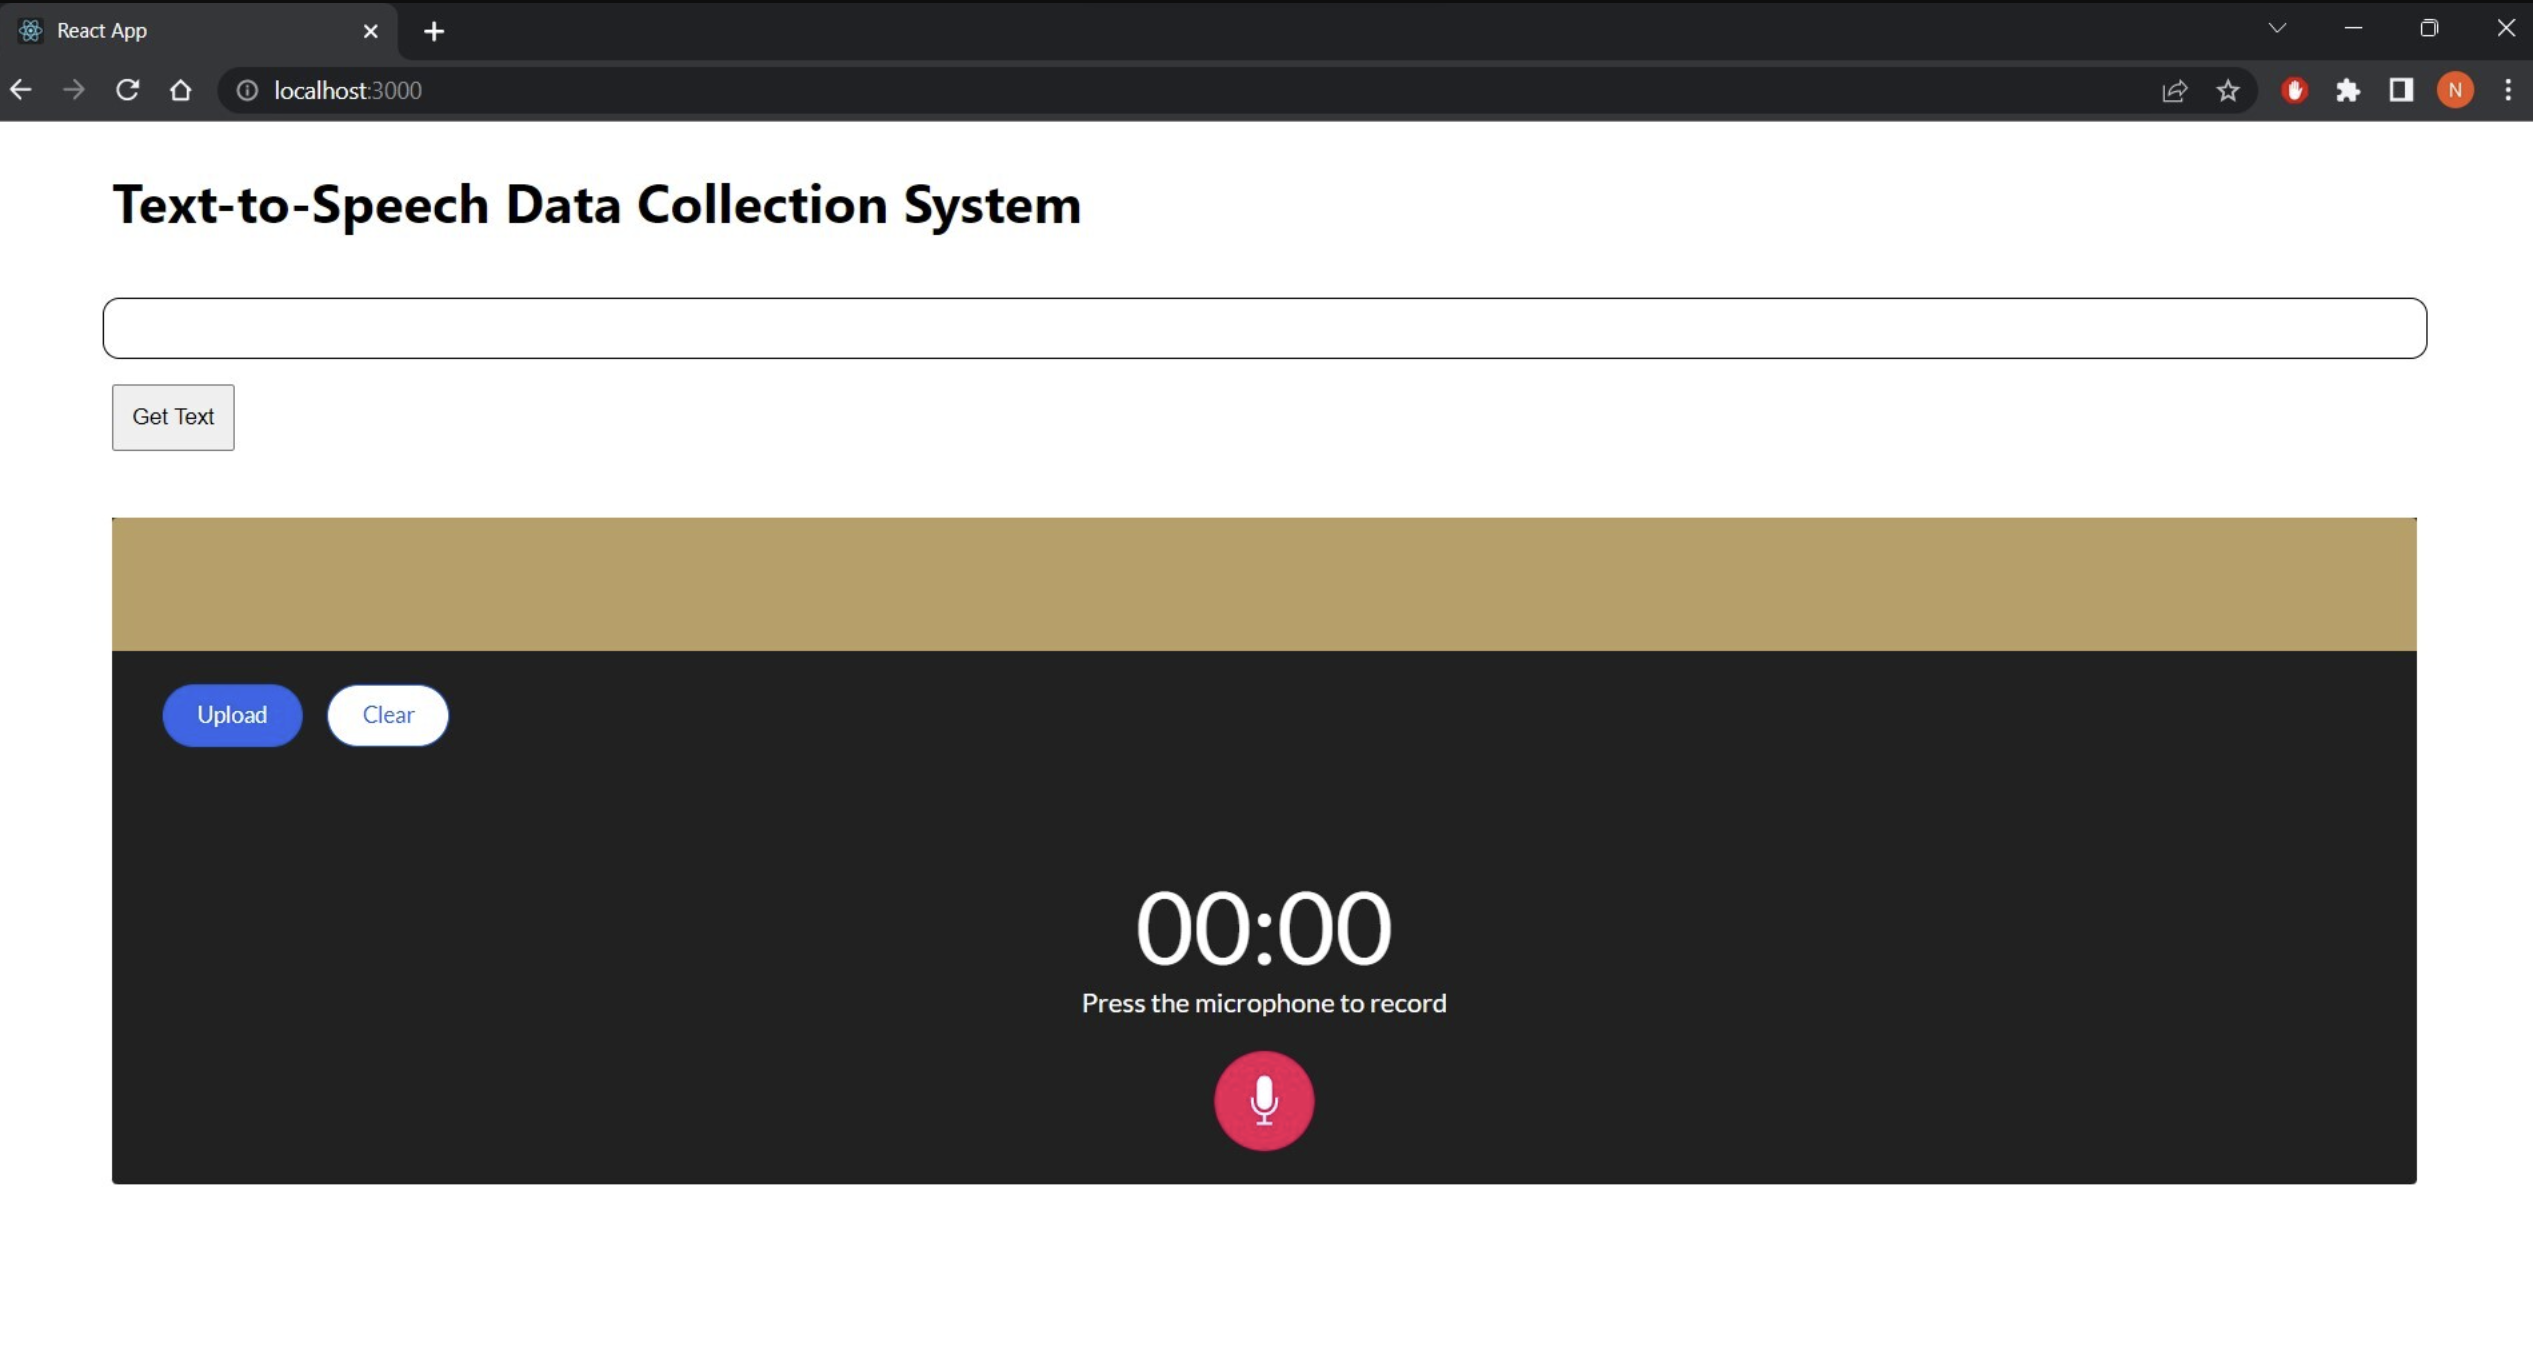
Speech-to-text models need audio paired with text, and low-resource languages lack such corpora. This team project built the collection machinery: prompts and recorded audio flowing through Kafka topics, processed with Spark, orchestrated by Airflow, stored in S3, with FastAPI services and a React front-end for contributors.
Media